The GRC Vibe Coder's Playbook · Lesson 09 of 10
How Do I Keep a GRC Project Reliable After Launch?
A first release is the beginning of looking after your project.
All 10 Lessons · Jump to a Lesson
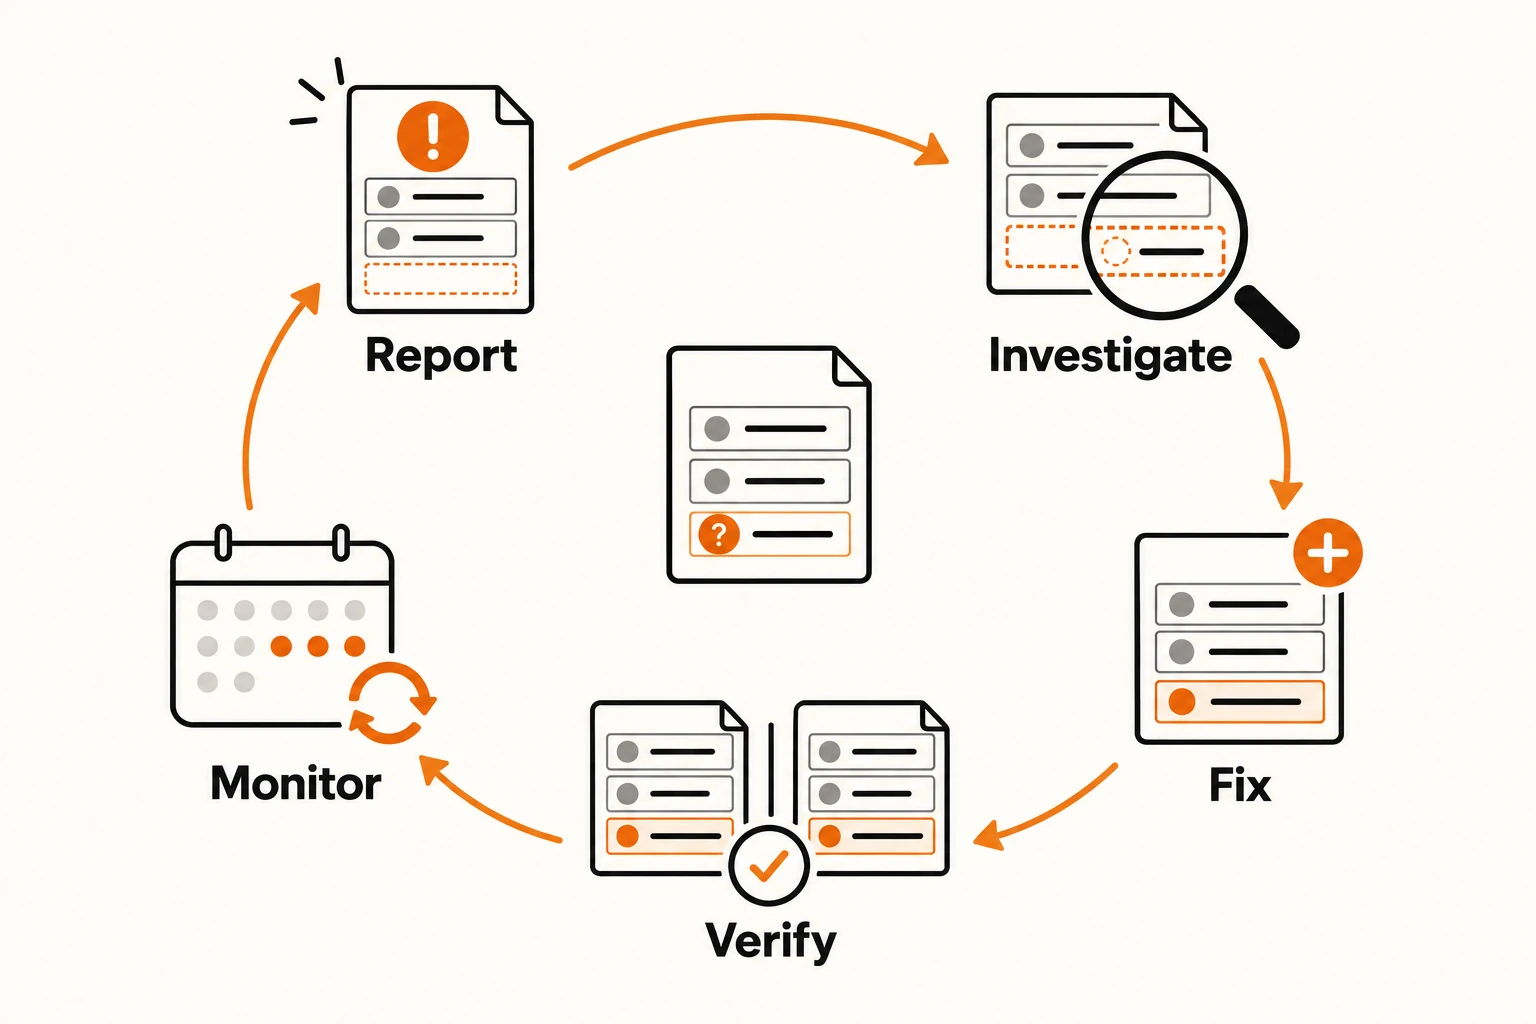
Imagine a teammate uses your tool and finds that an export leaves out missing answers. Fixing that problem is part of owning software after its first release. Describe the defect, investigate where it happens, make a small change, and check the result.
A release is a version shared for use; deployment puts that version where people can access it. A demo with fictional data is not automatically safe for confidential vendor records. As the tool grows, someone must own access, updates, errors, and recovery if a change goes wrong.
Follow One Export Defect to a Verified Fix
Notice and Record
A teammate reports that the CSV leaves out missing answers. Save a fictional sample and the expected output.
Investigate
Compare the screen and export. Find where the unanswered notification field disappears.
Fix and Test
Preserve scoring rules. Keep the missing value and reason in the CSV, then add a regression check.
Review and Verify
Inspect the change, record approval, and verify the released export. Keep recovery steps and a 30-day follow-up.
Do It Scared: Errors Are Part of Building
Something will break. A pull request may fail a test, a deployment may fail, a link may lead nowhere, or an AI agent may change the wrong file. You do not have to know every command before you start. Learn to investigate one failure at a time.
- Read the failure: Find the failing check in GitHub Actions or the deployment dashboard. Read the first useful error message, not just the red status.
- Find the boundary: Is the problem in code, tests, documentation, configuration, dependencies, or the deployment environment? Reproduce it locally when possible.
- Use the CLI when needed: Practice commands such as
git status,git diff, and the project's documented test command. Ask AI to explain a command before running it, especially if it changes files or infrastructure. - Fix and verify: Make the smallest justified change, update guiding text and tests when requirements change, rerun checks, and inspect a preview before merging when one is available. After merging and deploying, verify the production site.
- Keep the lesson: Record the cause, fix, and prevention in the PR or a short troubleshooting note.
A real example: While expanding this Playbook, a glossary test failed because it expected one way of writing lesson slugs, but the revised lesson data used another. The right fix was to make the route check understand both valid formats, not disable the test.
For GRC practitioners, this is also evidence of change management: the issue, investigation, correction, tests, and human decision form a traceable record. When the change affects security or risk scoring, review its impact before deployment.
Do it scared. Confidence grows from troubleshooting and shipping small improvements, not from waiting until you can predict every error.
The GRC Connection
Operate the control over time. Track changes, owners, incidents, exceptions, evidence retention, and scheduled reviews.
Put It into Practice
Write a small pre-release checklist for a fictional-data demo, including who uses it, expected results, checks, and ownership. Set a 30-day follow-up to review errors, dependencies, and improvement ideas. Identify what extra work real data would require.
Build a Release and Maintenance Checklist
Before publishing a GRC tool, identify its owner, intended users, data sensitivity, access restrictions, logging, recovery approach, test coverage, and escalation path. Keep a record of scoring-rule changes and approvals.
Open a follow-up GitHub issue for a 30-day check: review dependencies, validate access, inspect incidents or errors, revisit open exceptions, and prioritize technical debt.
What Good Looks Like
You have a checklist, a named person responsible, and a 30-day review task.
Check the result yourself. Save the decision or next step in GitHub so you can return to it later.